Inference now drives two-thirds of AI workloads, changing where chips get deployed
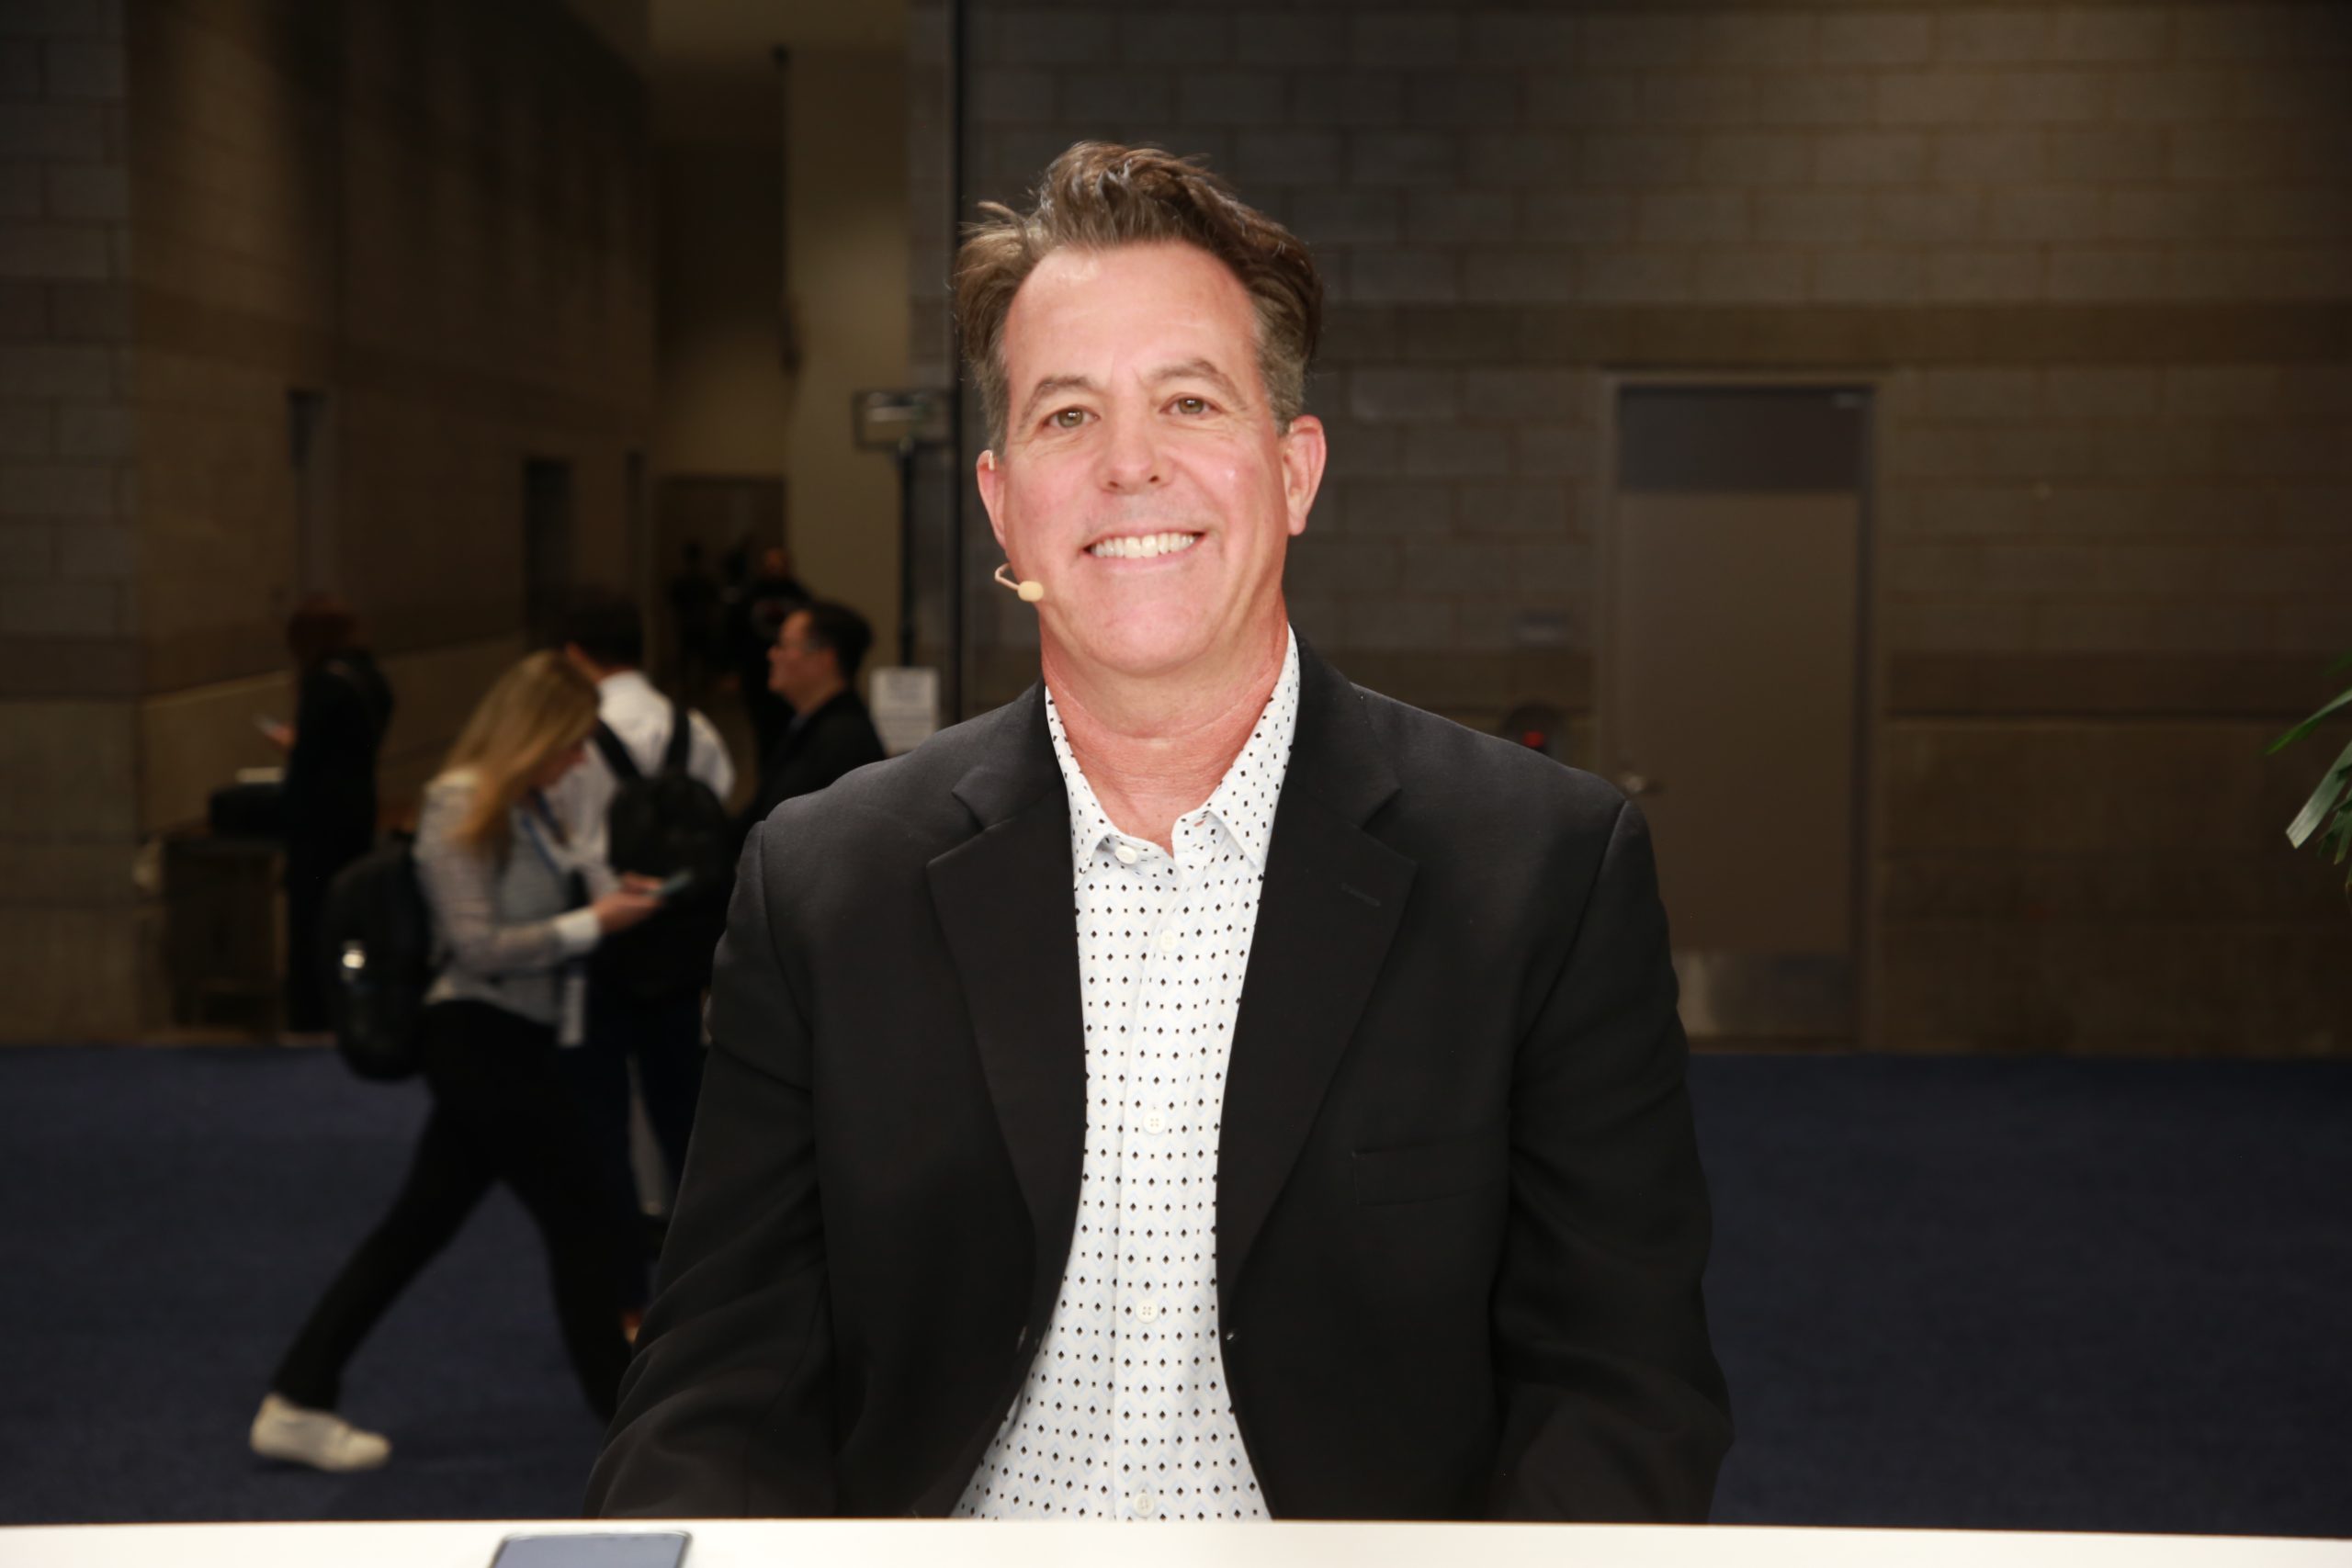
SiliconAngle reports that AI spending is shifting from large training clusters toward smaller, quickly built sites. Modular data centers are becoming a natural fit for inference workloads, and the outlet says power, cooling and memory supply now shape where tokens get generated as much as raw chip performance does. The piece features Positron AI Inc., which says inference now makes up two-thirds of AI workloads and that its low-power inference servers use commodity memory and let operators go from land and power to tokens in 90 to 120 days.
Based on SiliconAngle's report - only one outlet has covered this so far. Read the original.Coverage 1 source · 1 report
Chronological.
-
Inference now drives two-thirds of AI workloads, changing where chips get deployed
AI spending is shifting from giant training clusters toward smaller, quickly built sites, and modular data centers are becoming a natural home for inference workloads. Power, cooling and memory supply now shape where tokens get generated as much as raw chip performance does. Inference-first chipmakers want to capture that shift. Positron AI Inc., which raised […] The post Inference now drives two-thirds of AI workloads, changing where chips get deployed appeared first on SiliconANGLE .
Related stories
 Technology
Signal Is Fighting to Keep AI Agents Out of Your Private Messages
 Technology
Trump says he won't allow U.S. companies to build data centers outside the country
 Business
Trump says there could be a 'positive spin' from the latest FBI database hack
 U.S.
I’m a priest. Silicon Valley’s search for the ‘soul’ of AI is deeply troubling | Rev Kevin Deal
Discussion 0 comments